Connect data.Govern context.Feed AI.
DataFloem brings integration, transformation, cataloging and query together on Kubernetes. Build pipelines on a canvas or in Python, run them on public cloud, private cloud or on-premises, and keep your data in open formats.
The data platform behind teams in banking, retail, automotive and manufacturing.


Start where your data already lives.
From legacy databases to object storage and lakehouse catalogs, connect each system once and reuse it across every project. Administrators decide which teams can read and write each source.
RDBMS
PostgreSQLOracleSQL ServerAzure SQLAzure SynapseMySQLTeradataVerticaClickHouseTrino
Cloud Database
BigQuery
Cloud Storage
Azure Data Lake Storage Gen2Azure Blob StorageGoogle Cloud Storage
Object Storage
Amazon S3S3-compatible stores
NoSQL
MongoDBElasticsearch
Catalog
Iceberg REST catalogsJDBC catalogsFile catalogs
Python Script
Any system you can reach from Python
- FormatsCSV, Parquet, ORC, JSON with Snappy or Gzip
- ReadsFull or incremental, with your own increment script
- WritesAppend or overwrite, with pre and post queries
- ConnectionsSSL/TLS and driver options, secrets kept masked
Draw the pipeline. Read the rows. Catch the drift.
Build a new integration on a visual canvas instead of writing it from scratch. Each node opens a typed form, so a mismatched join key shows up while you build, not when the job fails.
- Versions. Every job keeps numbered versions, so you can change a pipeline without losing the one that runs.
- Copy, paste, group and notes. Organize a large job the way you would a large file.
- Flow parameters. Static or expression values, used in any field as $$name.
- Auto layout and undo. One click tidies the graph, and you can undo up to fifty steps.
- Source and TargetAny connector family, read and write.
- SelectKeep, rename or drop columns.
- ExpressionComputed columns in Spark syntax.
- FilterNested rules and condition groups.
- JoinLeft, right, full outer and cross, with typed rules.
- AggregationSum, avg, min, max, count, distinct count, std dev.
- UnionUnion or Union All, mismatches shown per column.
- DistinctOn all columns or the ones you pick.
- SortAscending or descending keys.
- RepartitionPartition count and partition columns.
- SamplingRandom or stratified, with both outputs kept.
- SQLWrite the step as a query, declare the output.
- WranglerCleanup steps with a live draft run.
- PythonA script step with one or more output tables.
Joins you can read.
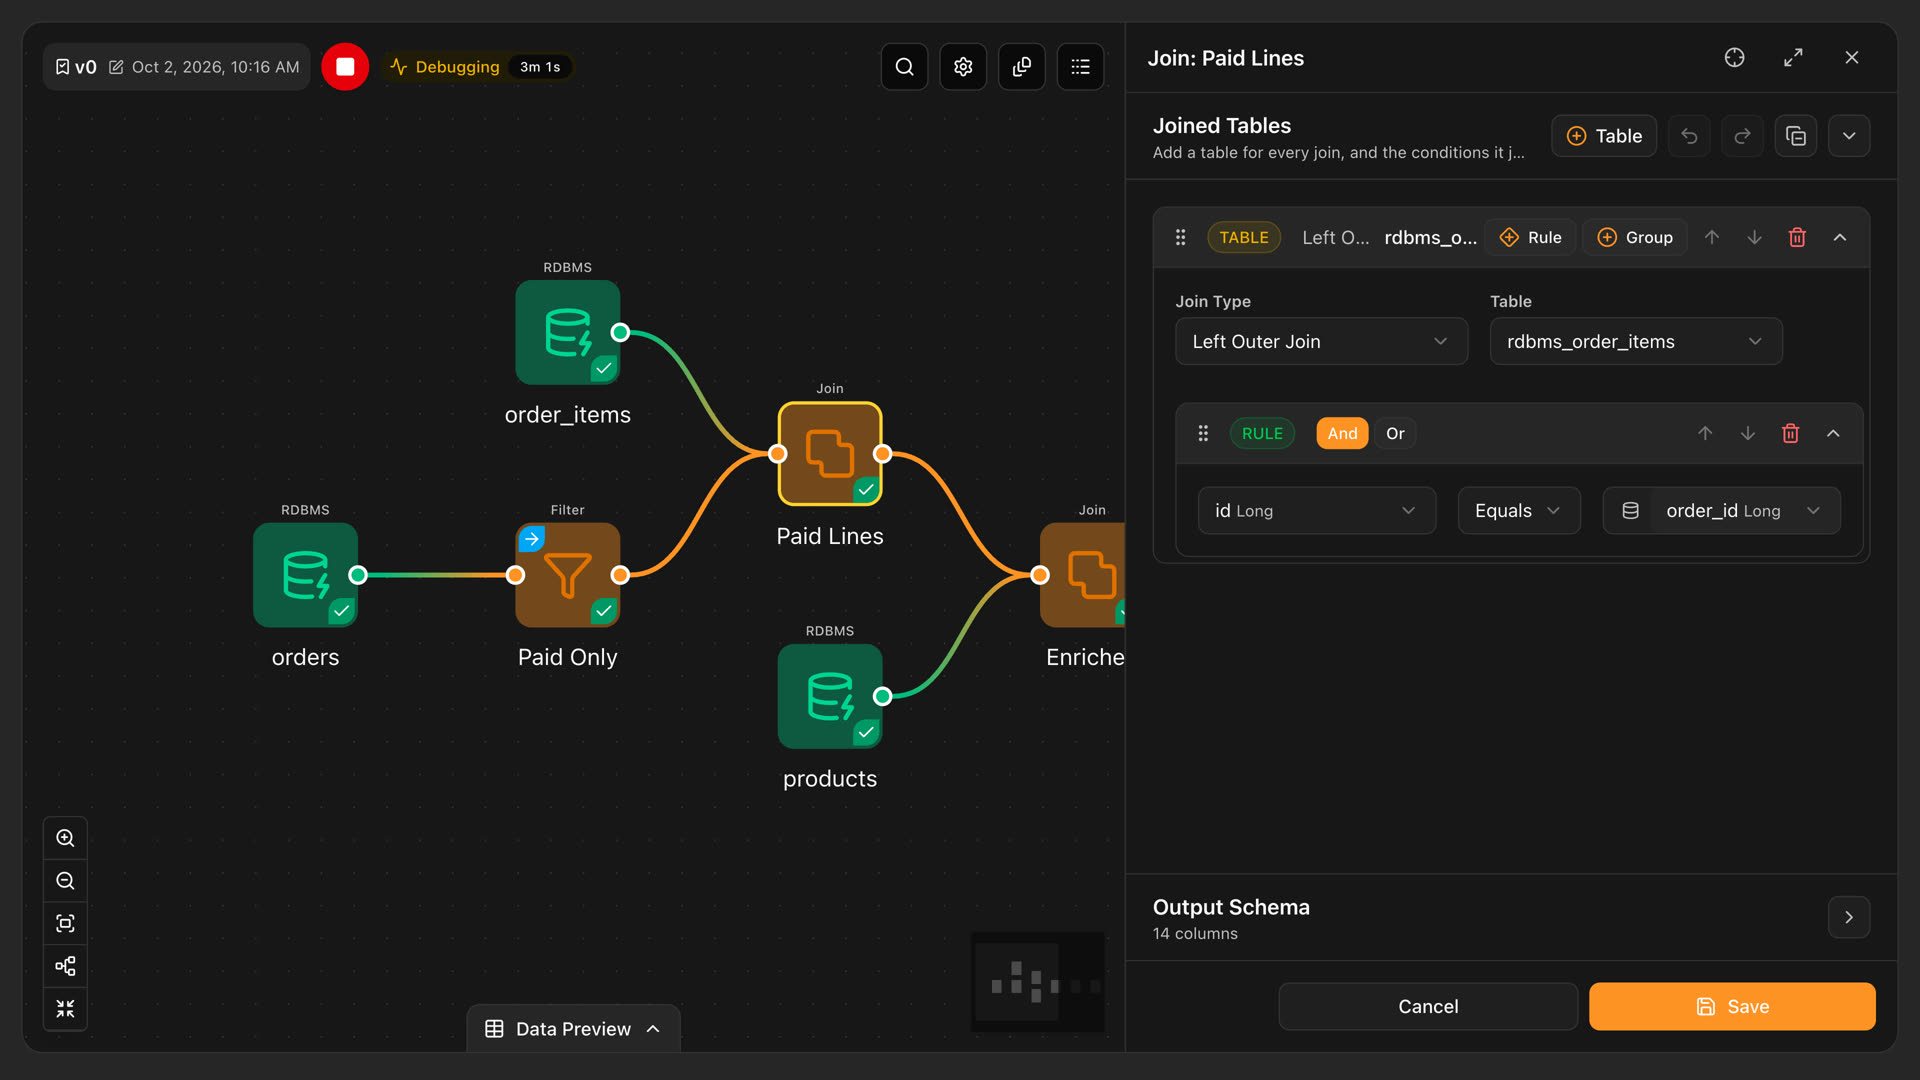
Add a table, choose the join type, and build the condition from rules and groups. Each column shows its type next to its name, so a key mismatch is visible before it reaches the engine. The output schema sits at the bottom of the panel with its column count.
Check the rows at any node.
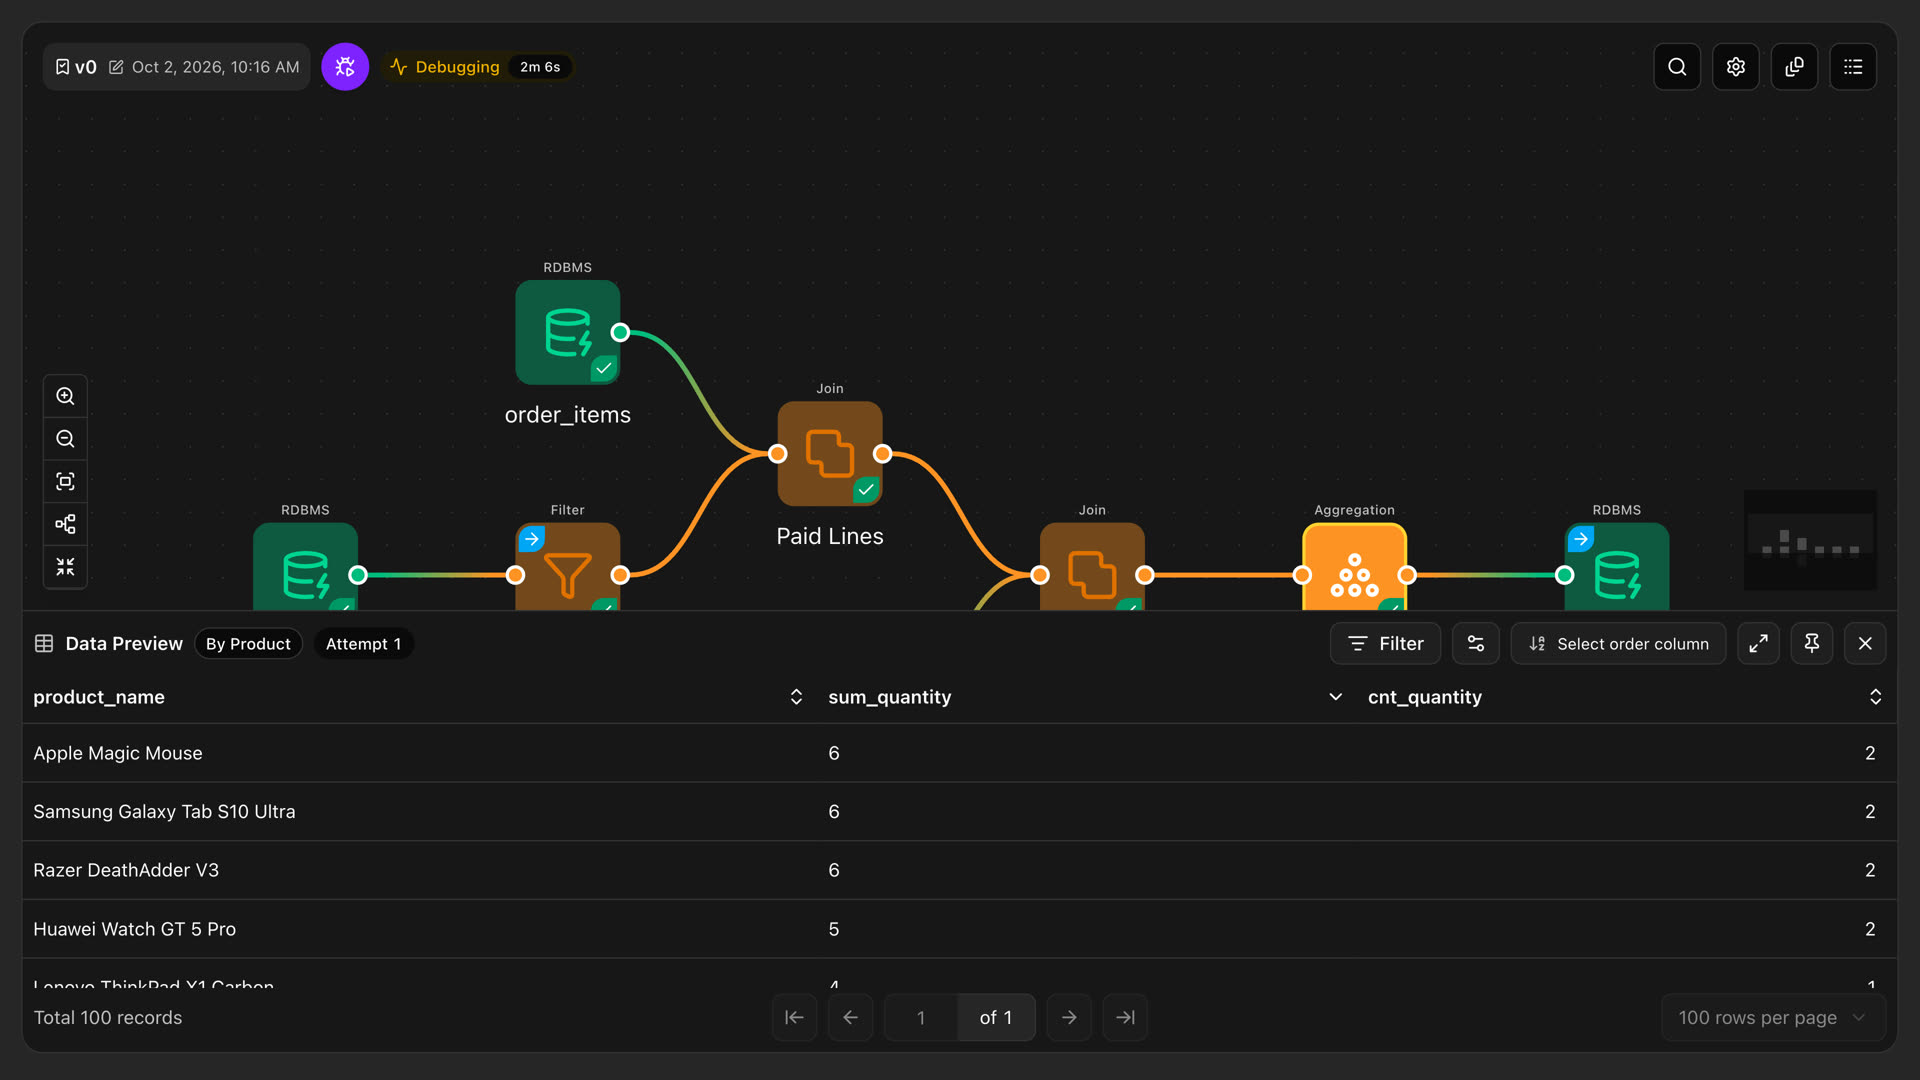
Run the pipeline up to the node you are working on and open its rows in place. Filter, sort and page through the result without leaving the canvas.
- Partial runs. Select the nodes you care about and run only them.
- Compare before and after. Each debug run keeps its own preview, so you can see what your change did.
- Status on the node. Running, finished and failed states show on the canvas. A node whose settings, wiring or upstream changed since its last run is marked stale.
A column changes upstream. Only the affected nodes ask for review.
With dozens of sources changing on their own schedules, schema changes are a daily fact. Every node remembers the columns it was saved with. When a source gains, loses or retypes a column, DataFloem marks only the nodes it reaches. You decide what the change means.
A source changes.
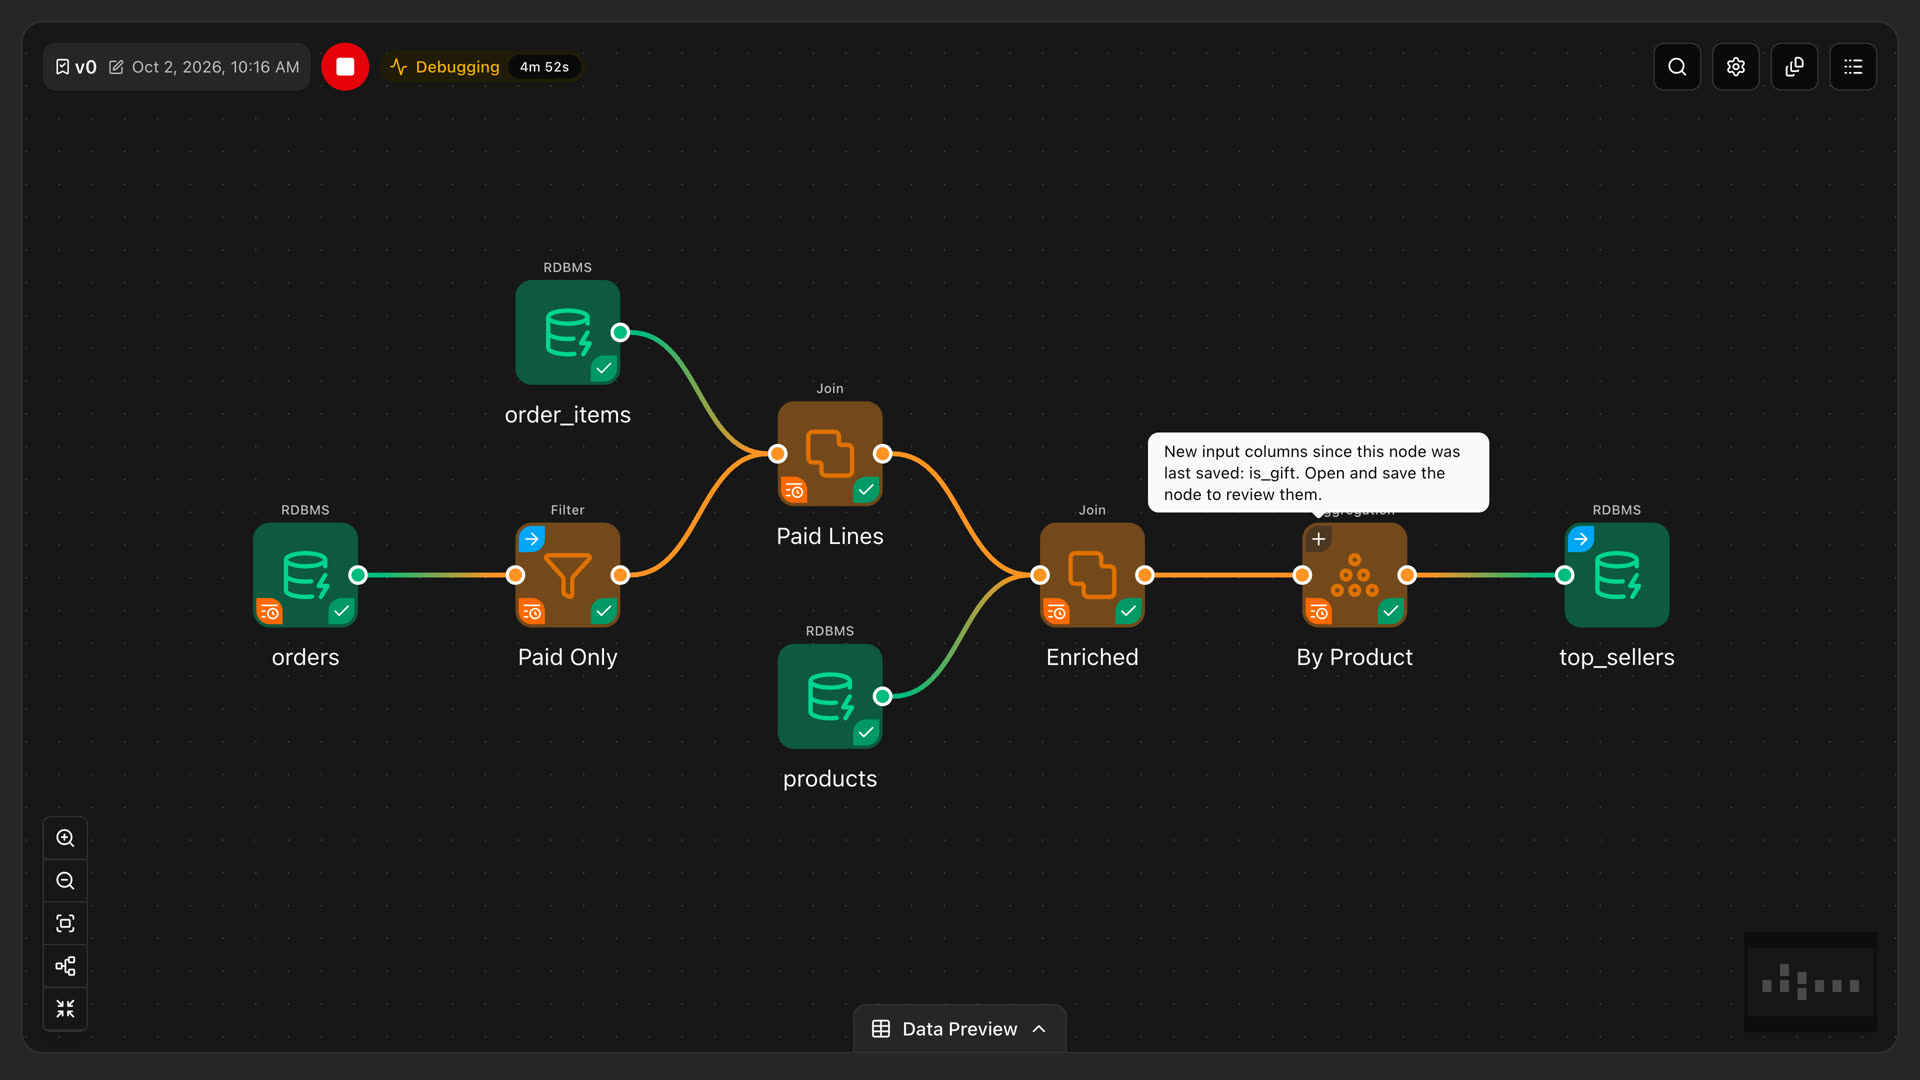
If a column only changed position, DataFloem fixes the reference for you. Nodes whose output could change get a marker that names the exact columns.
The canvas follows it.
Column ids that only moved are repaired for you. Nodes whose meaning could change get a marker, with the exact column names in the tooltip.
A person signs off.
Open the node and choose: adopt the new columns into its output, or keep them excluded. A full run warns you while reviews are still open.
Some work belongs in code. Keep it in the same project.
For ML feature preparation, custom integrations or anything the canvas does not cover, write Python in Jupyter Lab, package it as an image, and run it on your own Kubernetes cluster with the same connections and access rules.
Write in Studio
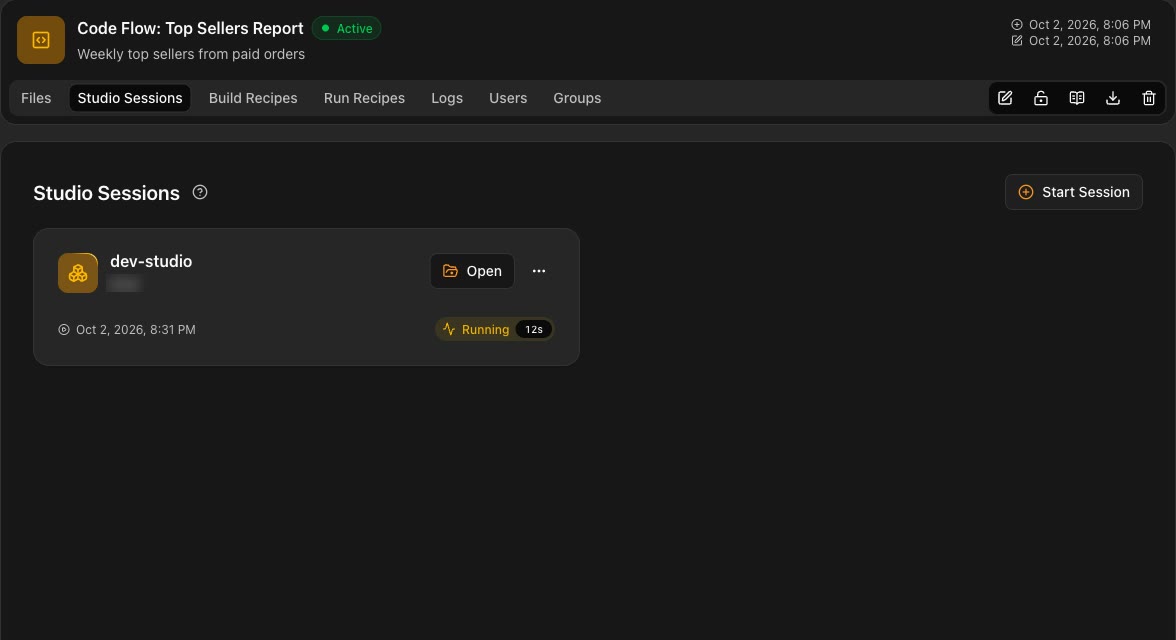
Open a Jupyter Lab session on a Studio assigned to the project. Save the files you want to keep to the Code Flow.
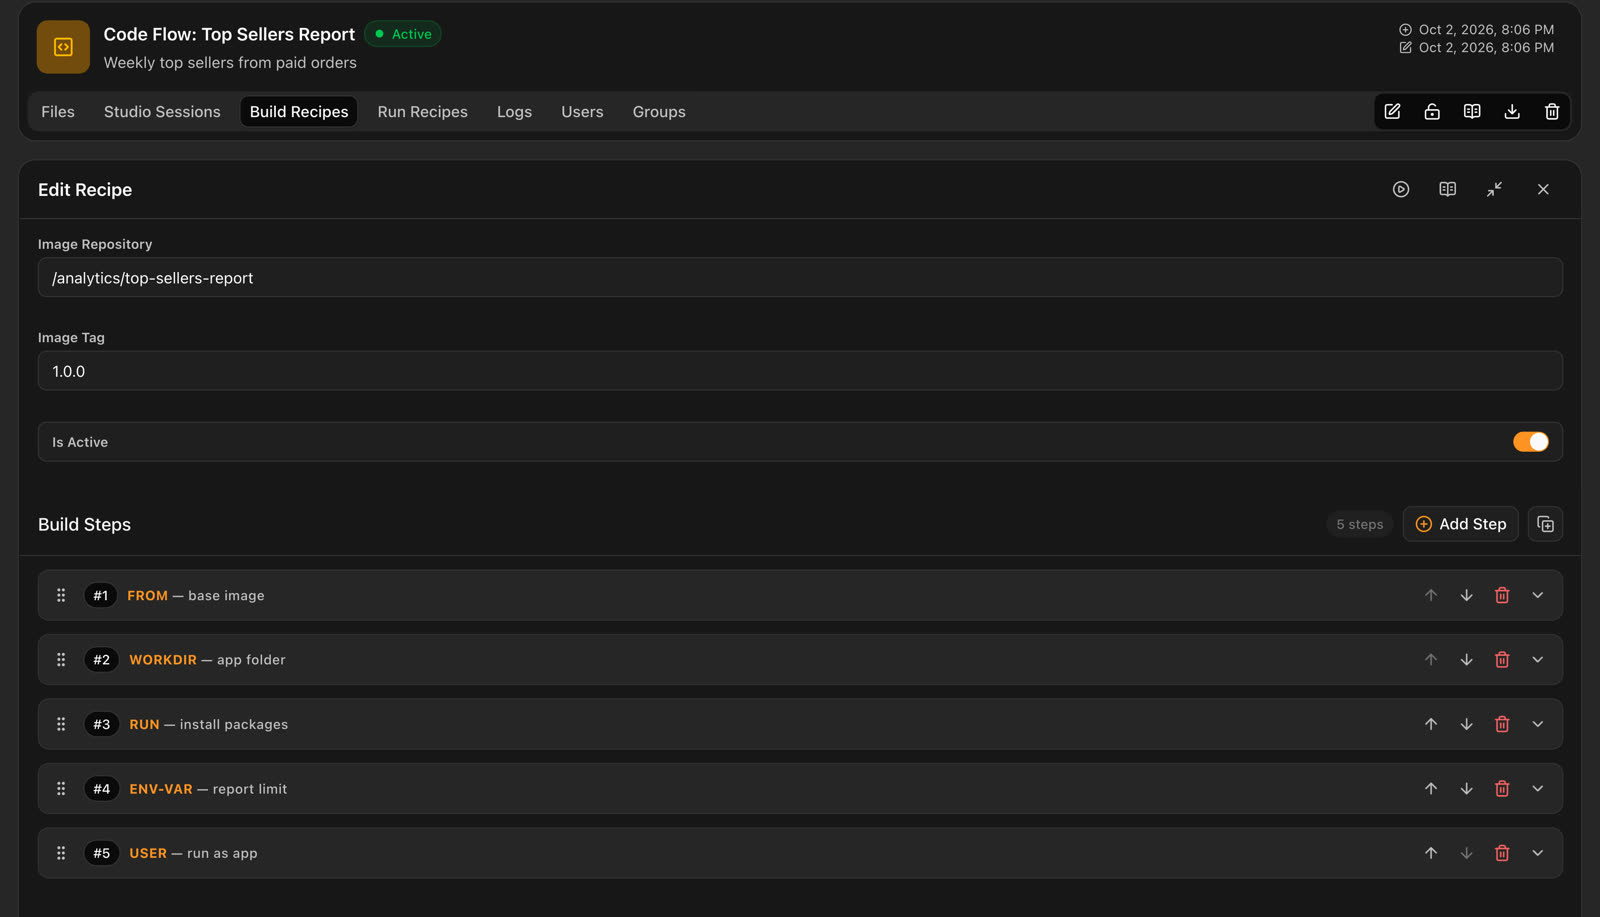
Package it
Set the image repository and tag, then order the build steps. An agent on your own server builds the image and streams the log back.
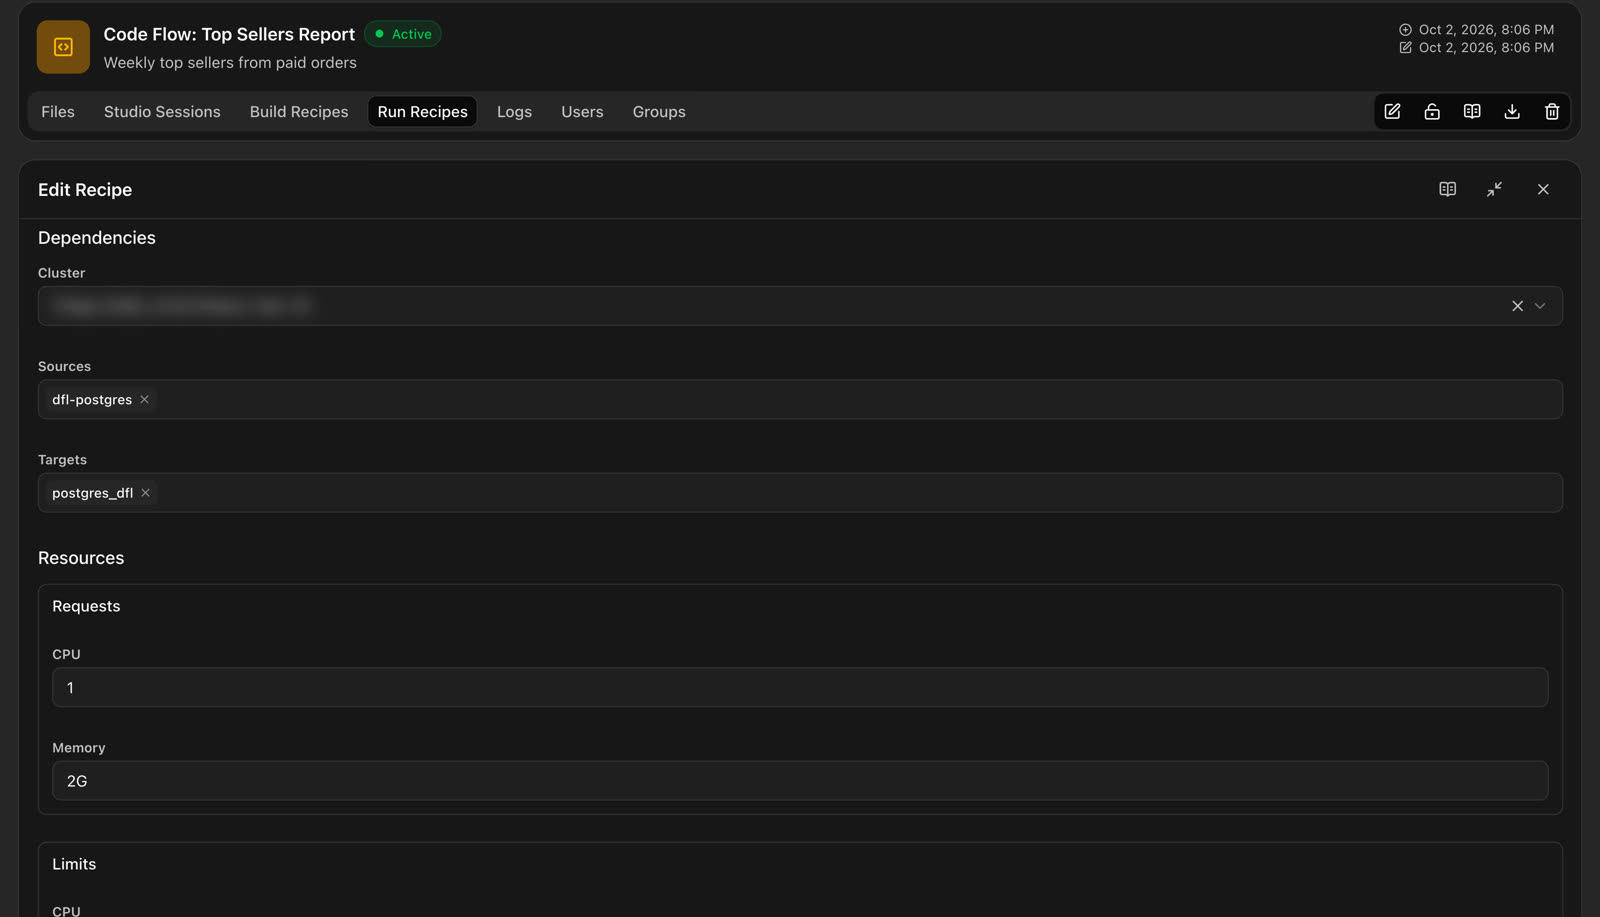
Run it on your cluster
Pick the cluster, the project's sources and targets, environment and secret settings, and the CPU and memory requests and limits.
Catalog it, query it, control who sees it.
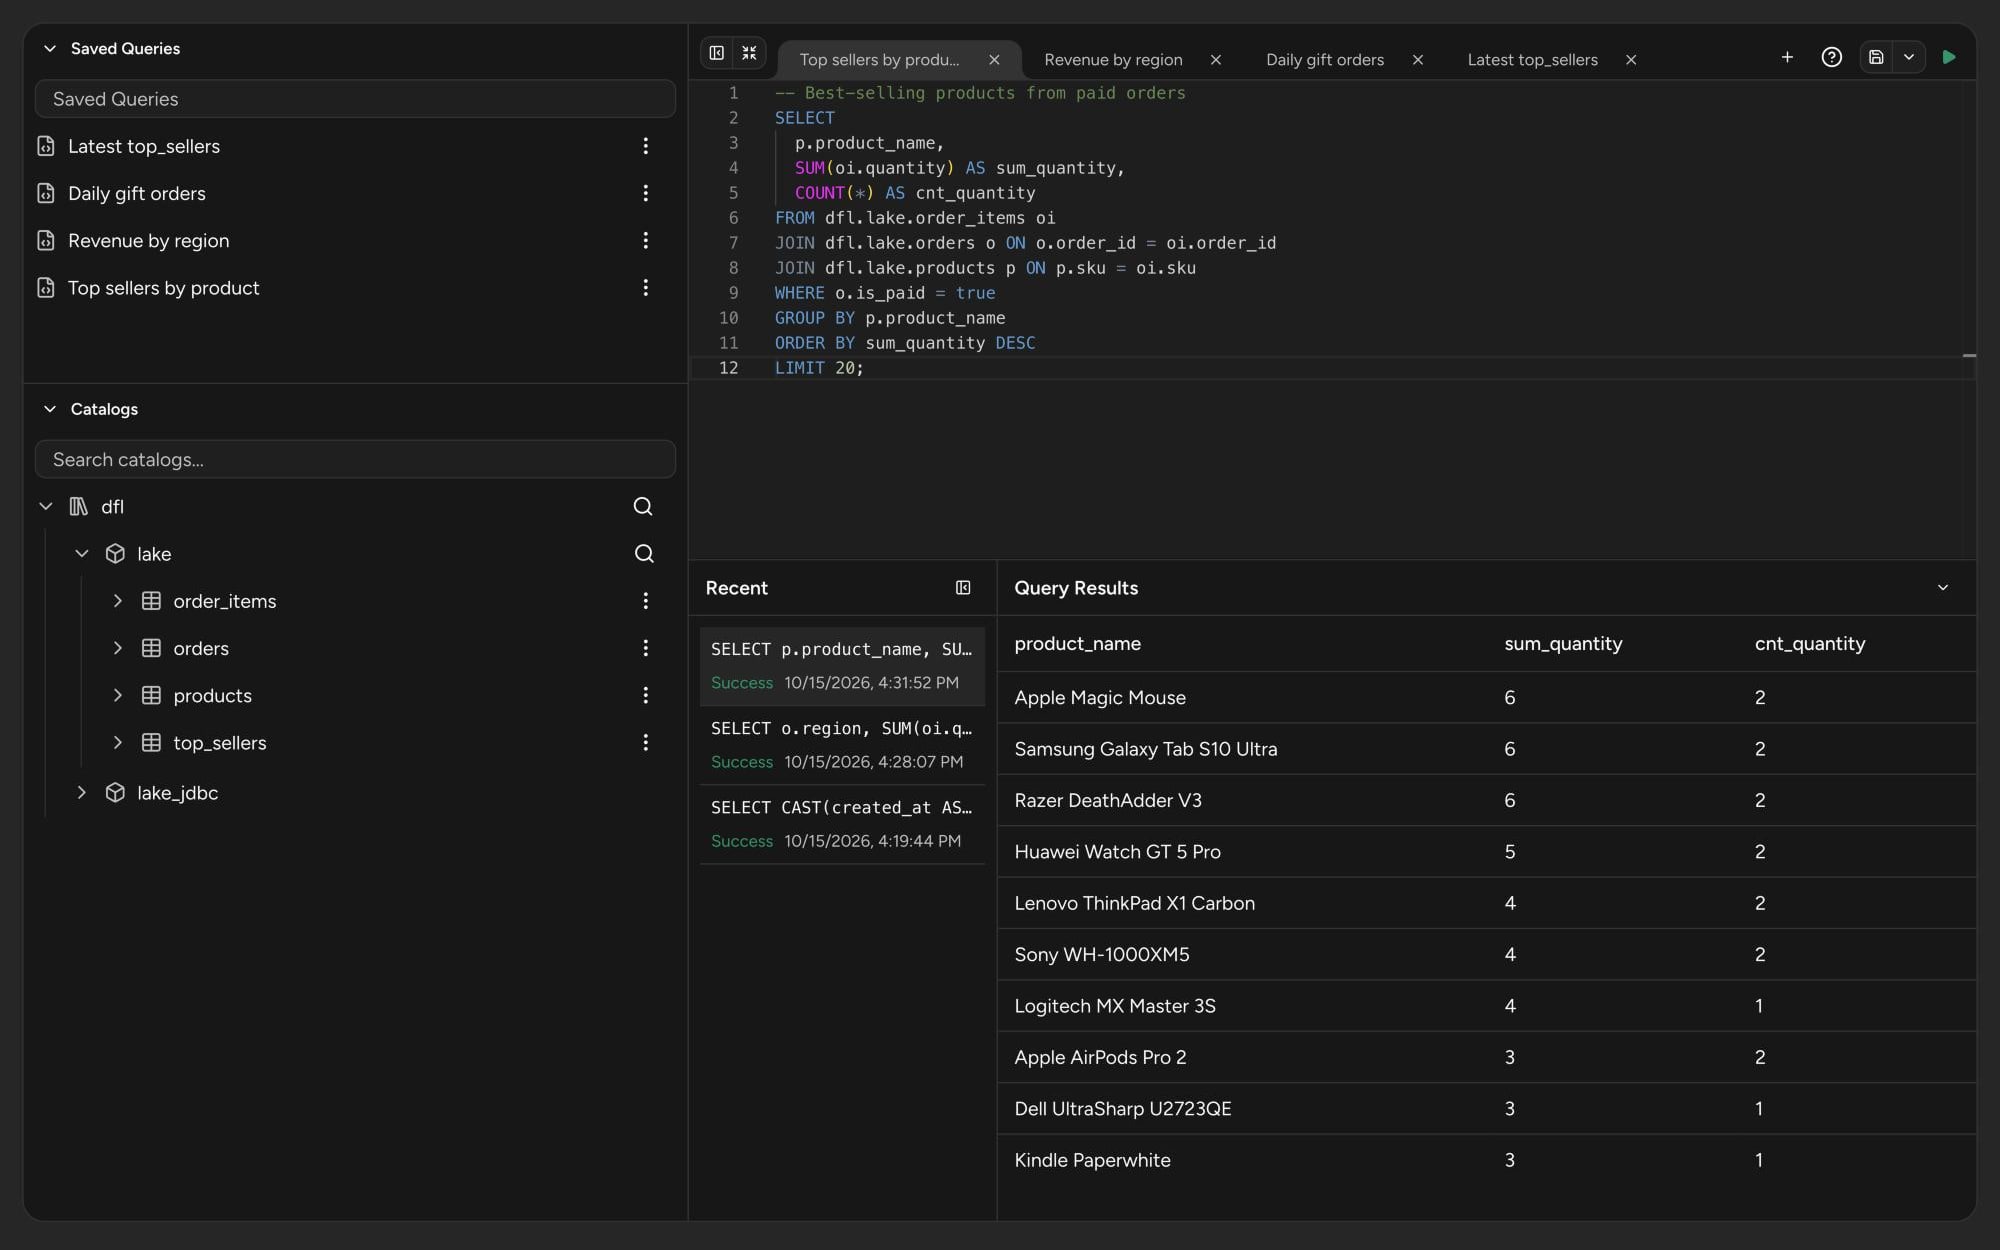
Your lakehouse tables in Iceberg, Parquet and other open formats, organized in catalogs, queryable from the same workspace and ready to feed AI projects. Analysts browse schemas, run SQL on the engine you pick, and see only the tables their role allows.
- Tabs and saved queries. Work in several tabs at once, save the queries you reuse, and find earlier runs under Recent.
- Results as they arrive. Rows stream into the results panel while the query runs, and you can stop it at any time.
- Catalogs. Iceberg, Parquet, CSV, ORC and JSON tables in JDBC or file namespaces. Create tables from a source in bulk and alter their columns.
- Access down to the table. Policies, roles and bindings decide who can read each table.
Spark does the processing. Kubernetes does the scaling.
Kubernetes clusters and Studio workspaces with worker counts, idle timeouts, node selectors and tolerations. Configuration profiles keep shared variables and secrets in one place.
Export a job, Code Flow, project, folder or whole namespace to a file and import it into another environment.
Runs on any infrastructure you choose. Your data stays there.
DataFloem is cloud-native and runs wherever Kubernetes runs: AWS, Azure, Google Cloud, a private cloud or your own data center. You install it next to the systems it reads, so your data and credentials never leave your environment.
- Your computeJobs, partial runs and Studio sessions run on Kubernetes clusters you own, with the CPU and memory limits you set.
- Your build chainA build agent on your servers packages Code Flows and pushes the images to your registry.
- Your connectionsConnections use SSL/TLS. Passwords and secret driver options stay masked in the product.
Governed from the first connection.
Catalogs, schemas, access rules and audit logs keep the context around every table. Access follows the structure of your organization: every job, Code Flow and connection lives in a project, and every project has its own users and groups.
A clear hierarchy
Namespaces hold folders, folders hold projects, and projects hold the work. Infrastructure is assigned to a project, or a person asks for it and an owner approves the request as a task.
namespace analytics
└ folder commerce
  └ project revenue
    ├ jobs · code flows
    ├ sources · targets
    ├ clusters · studios
    └ users · groups
Access on every resource
Each job, Code Flow, connection and cluster has its own users and groups, with separate rights to list, read, change, run, use, delete and share.
Sign in with your directory or your identity provider.
A record of who did what
Request and change audit logs, with retention you set and tracking you turn on per resource type.
Open jobs show who else is on the canvas. The first edit takes a lock, others see the job read-only, and an administrator can release a lock that was left behind.
Where does my data go?
Nowhere outside your network. DataFloem is self-hosted: you install it in your data center or your own cloud account. Jobs read from and write to your systems directly, and your data and credentials stay inside your network.
What runs my jobs?
The Kubernetes clusters you register in DataFloem. Each run goes to the cluster you choose, with the resources that cluster allows. Expressions are written in Spark syntax.
Can I write code instead of drawing nodes?
Yes, at two levels. Inside a job, the SQL and Python nodes let you write one step as code and declare its output. For a whole pipeline in code, a Code Flow holds files from a Jupyter Lab or VS Code session, a Build Recipe that packages them, and a Run Recipe that runs them on your cluster.
What happens when a source table changes?
DataFloem compares the columns each node was saved with against its input now. Column ids that only moved are repaired. Nodes whose output could change get a review marker that names the columns, and a person decides to adopt or exclude them. A full run warns you while reviews are open.
Can I check the results before I run the whole job?
Yes. Select the nodes you care about and run only them, then open the rows of any node in the Data Preview: filter, sort and page through them. Nodes whose settings, wiring or upstream changed since their last run are marked stale.
How do I move work from development to production?
Export a job, a Code Flow, a project, a folder or a whole namespace to a file, and import it into the other environment. Flow parameters keep values that differ between environments out of the job itself.
How do several engineers work on the same job?
Everyone on an open job sees who else is there. The first edit takes a lock and the others see the job read-only until it is released; an administrator can release a lock that was left behind. Every job keeps numbered versions.
How do people sign in, and who can see what?
People sign in with LDAP or your identity provider: Okta, Microsoft, Google or Keycloak. Every resource has its own users and groups, with separate rights to list, read, change, run, use, delete and share. Catalog policies go down to a single table.
How is DataFloem licensed?
The Developer Edition is free and coming soon: you will register with your email from the setup screen. The Enterprise Edition uses a license that sets the features and limits for your organization, and administrators upload, renew and revoke it in the product.
Start free. Grow into Enterprise.
Both editions run on your infrastructure and keep your data in open formats. Start with the Developer Edition when it is released, then move to Enterprise as your platform grows.
Free to start
Build jobs and Code Flows on your own installation, free. It is almost ready: leave your email and we will tell you the day it is released.
About Developer EditionThe full platform, sized to your organization
Your license sets the features and limits: users, namespaces, clusters, CPU and memory, retention. Administrators upload, renew and revoke it in the product.
- LDAP and single sign-on
- Request and change audit logs
- Build agents on your own servers
- Catalog access policies
Give your data a shape.
See how DataFloem fits your sources, your infrastructure and your team. We will walk you through the platform with a use case from your own organization.